Introduction
The line between a verbose AI response and a precise decision is narrowing. In a landscape dominated by large language models that excel at generating essays, a new class of model focuses exclusively on fast, structured output. TypeSafe's Jev project, launched in September 2026, introduced the concept of System One models that are fast, single-pass neural networks that output typed choices rather than free-form text. This guide distills the top 20 open-source options you can run on your own hardware, ranked for enterprises with deep GPU budgets and power users working with a single 32GB card.
What Happened
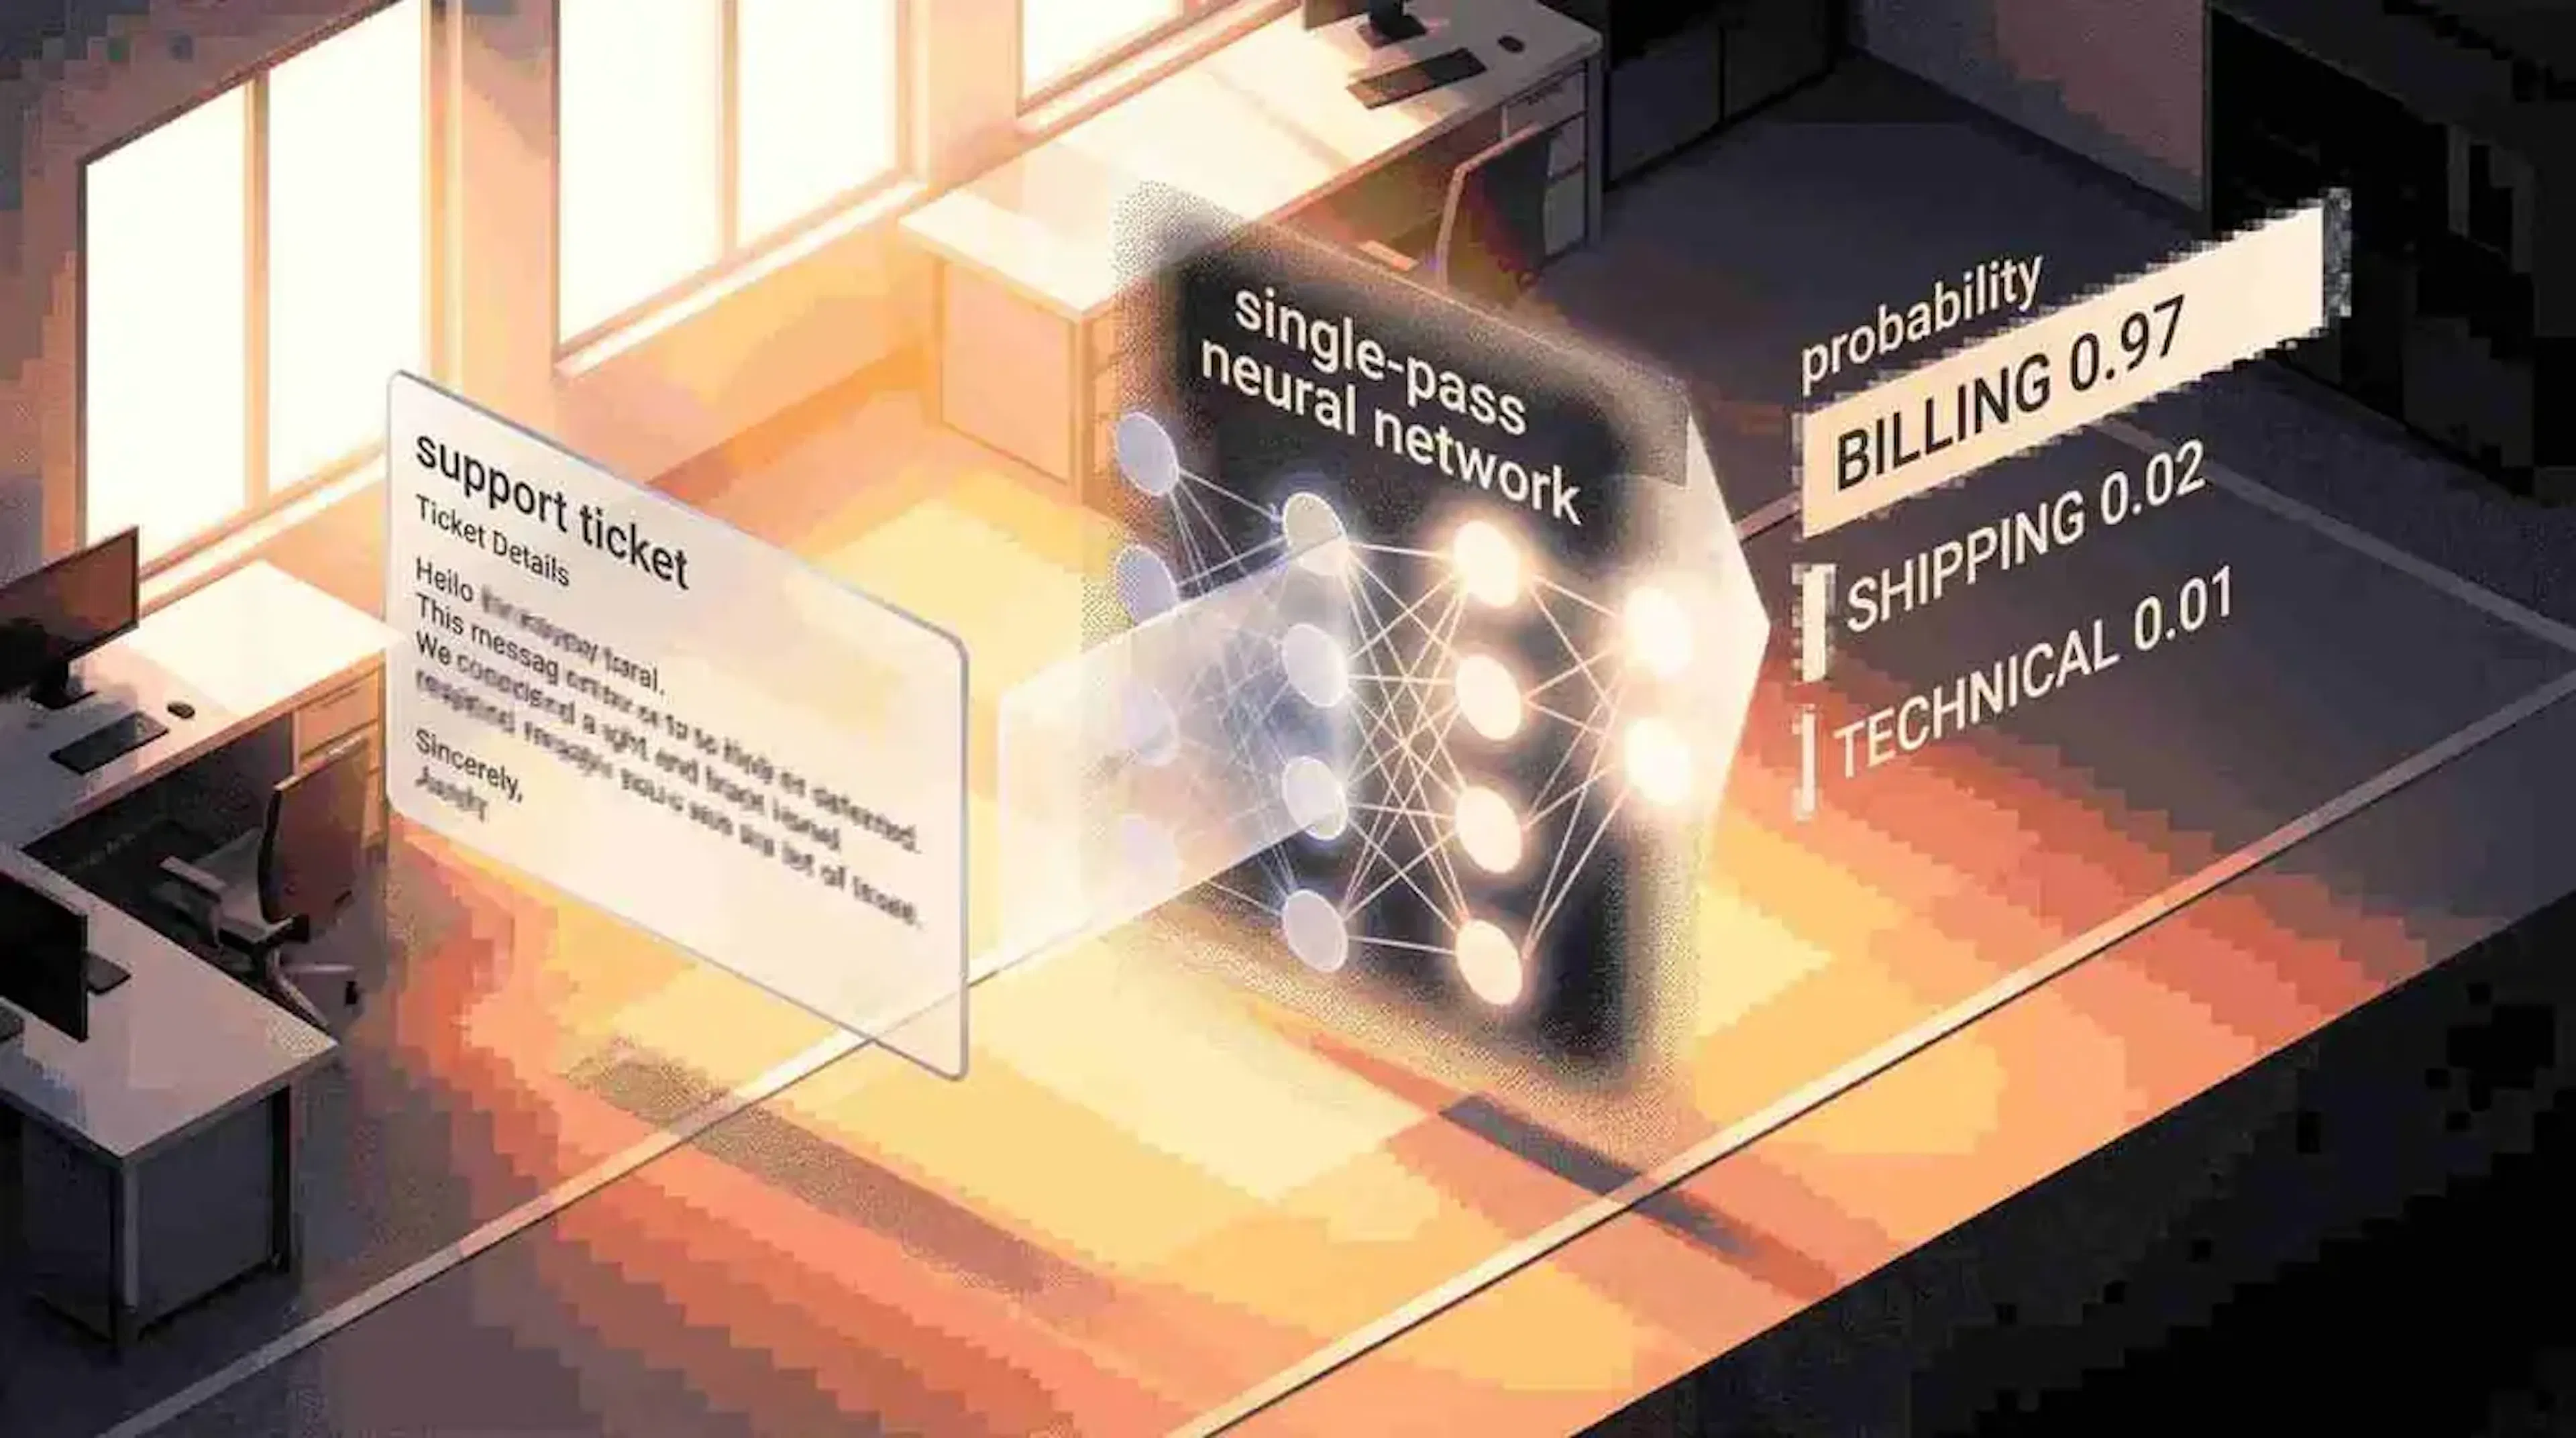
Last month, a frontier LLM was asked to categorize a support ticket into billing, shipping, or technical. It responded with four paragraphs. The author needed a single word and a confidence score. That mismatch between an LLM's tendency to elaborate and the need for immediate, structured decisions is where this new model class lives. Community tracking quickly surpassed 160 entries, and many open models now outperform the original hosted versions. This article organizes the leaderboard into two lists: one for enterprises with data-center GPUs, and another for power users limited to 32GB of VRAM.
Why This Matters
Running models locally eliminates API costs, removes data privacy risks, and lets you iterate without rate limits. The article explains why accuracy and speed matter differently depending on your hardware: enterprises can size hardware to the model, while power users must fit within a 32GB limit. Calibration error (ECE) is highlighted as a critical column, if you'll act on confidence scores, a high ECE can undermine trust. The dual-list approach ensures both accuracy-focused and speed-focused workflows have curated options.
Key Takeaways
- Two ranking lists. The Enterprise list ranks models solely by full accuracy score, requiring Apache 2.0 licensing and downloadable checkpoints. The Power User list splits weight equally between accuracy and speed, restricting entries to 32GB VRAM or less.
- Hardware flexibility. Enterprise picks typically need a DGX Spark (128GB unified memory) or a data center GPU with at least 80GB. Power User models are built to fit a single 32GB card, often through quantization.
- Runtime diversity. Models can be served via llama.cpp, vLLM, SGLang, or specialized runtimes like Shisa SDK and Qev. Each supports the /v1/systemone format for consistent decision queries.
- Calibration awareness. Calibration error (ECE) varies widely across the leaderboard. If your workflow depends on confidence thresholds, models with high ECE may require temperature refitting before deployment.
- Speed vs accuracy tradeoff. Power User rankings reward speed half as much as accuracy. Models like Blink achieve median latencies around 25ms. Enterprise-focused d3 clocks in at roughly 97ms latency, and interactive feel differs significantly.
Conclusion
Whether you have a DGX Spark or a single 32GB card, there's a ranked open-source decision model ready for local deployment. The leaderboard updates weekly, so rechecking before commitment is advised. By matching model capabilities to your hardware and calibration tolerance, you can replace costly API calls with self-hosted precision and speed.


Discussion
Join the conversation
Thoughtful reactions, questions, and follow-up ideas help shape the next story.