Introduction
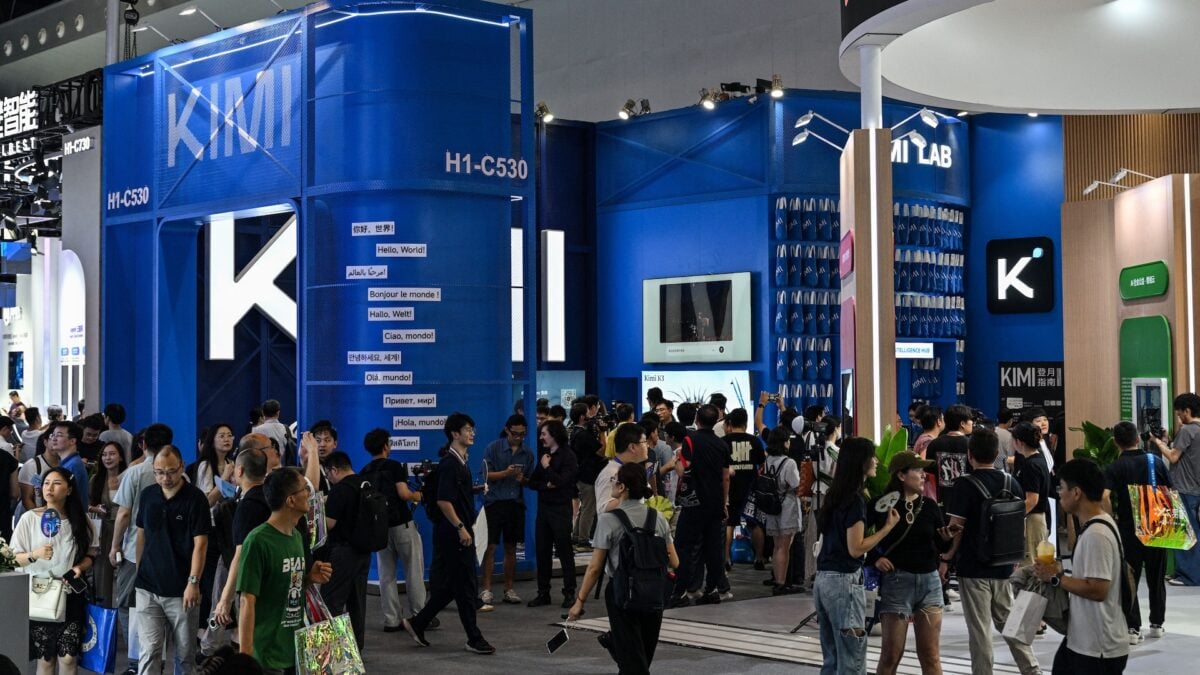
Kimi K3.1 Pro from Moonshot AI briefly captured attention on major AI leaderboards, charting fourth on the latest benchmark before a major index update reshuffled the standings. The model's strong initial performance highlighted the growing capabilities of Chinese-developed large language systems.
What Happened
Artificial Analysis launched Intelligence Index v5, introducing private test questions designed to prevent benchmark optimization. The new criteria dropped Kimi K3.1 Pro from fourth to ninth place and expanded the performance gap between open and proprietary models from three to twelve points.
Why This Matters
The v5 update reflects a broader move toward stricter, private benchmarking in AI evaluation. By reducing the influence of publicly available test data, the index reshapes how models are compared and highlights the growing divide between closed and open-weight systems.
Key Takeaways
- Kimi K3.1 Pro fell from fourth to ninth place after the v5 launch
- Sixty percent of v5 tests used held-out questions not previously public
- Google Gemini 4 Carbon now ranks first on the updated index
- The open-model performance gap widened to 12 points
- Moonshot AI has not released model weights, with plans to do so in November
Conclusion
Intelligence Index v5 marks a pivotal shift in how AI models are measured, prioritizing rigorous testing over short-term benchmark optimization. As the landscape evolves, the balance between open and proprietary systems will remain a central theme in AI development.


Discussion
Join the conversation
Thoughtful reactions, questions, and follow-up ideas help shape the next story.